Gramosoft Insights
Scraping Insights For Modern AI Data
Discover strategies for structured data, crawling, scraping, LLMs, and RAG to build smarter and more efficient data workflows.
Latest Articles
HTTP/2 Fingerprinting: Why Your Scraper Still Gets Detected
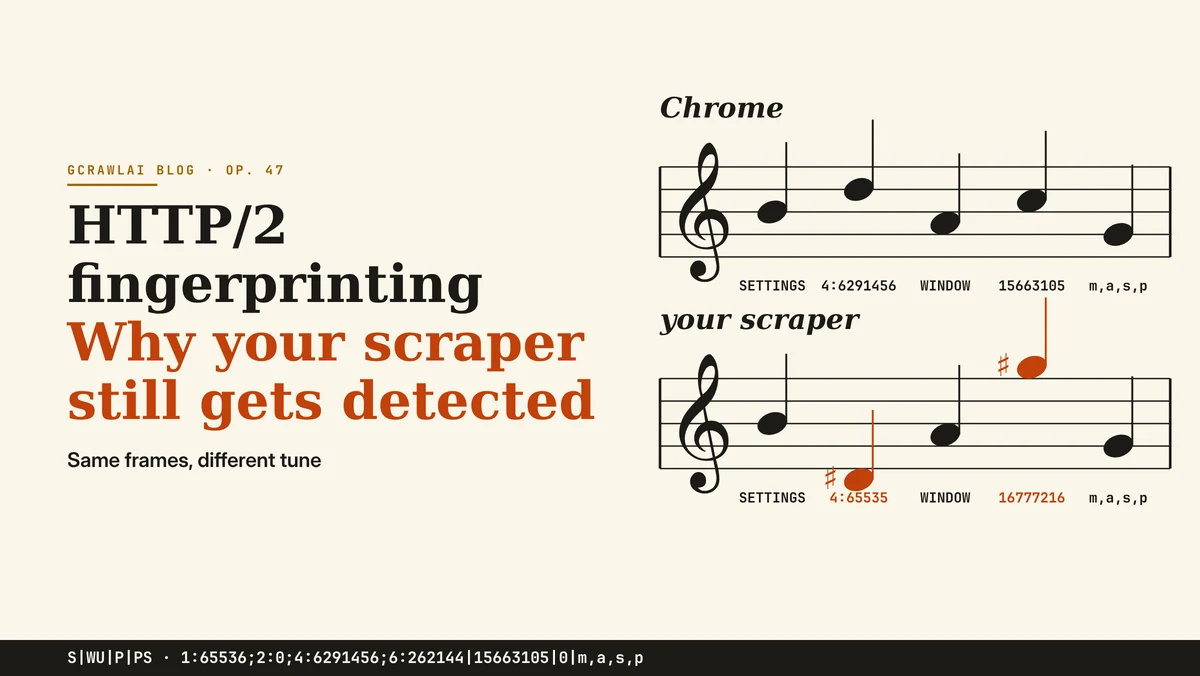
Why a scraper with perfect Chrome headers still gets detected: HTTP/2 fingerprinting reads the SETTINGS frame, the connection WINDOW_UPDATE, priority signals and pseudo-header order before the first request. How to read an Akamai S|WU|P|PS string, what six real clients sent to our own HTTP/2 server (requests, httpx, curl, Node, Go, Chromium), how to check your own client, why the cross-layer mismatch with TLS and headers is the real signal, HTTP/3 and QUIC, and the routes that hold up, including GcrawlAI.
How to Scrape AWS WAF-Protected Websites
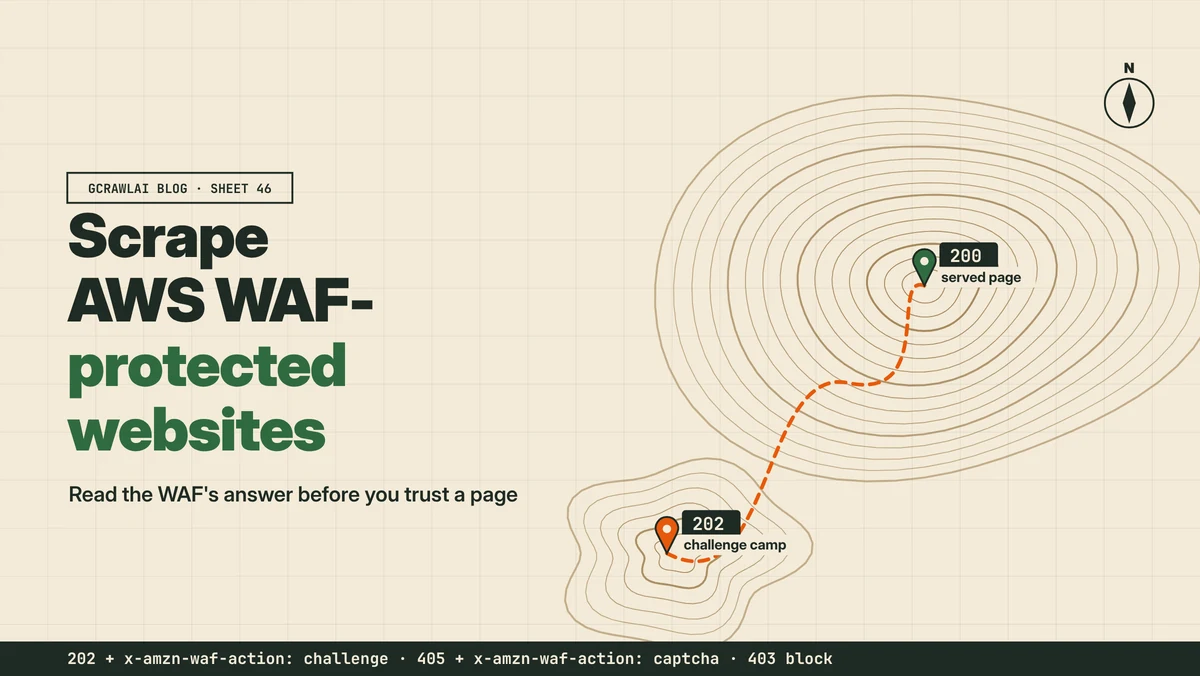
How to scrape AWS WAF-protected websites without storing challenge pages as data: what AWS WAF and its Bot Control are, the five rule actions (Allow, Count, Block, Challenge, CAPTCHA) and what each looks like to a scraper, why a 202 challenge passes requests' r.ok and httpx's is_success, how the aws-waf-token and immunity time work, how to read the x-amzn-waf-action header and validate fields, pacing under rate-based rules, and choosing between an official API, permission or a managed browser API like GcrawlAI. With our own local lab results and pricing.
How to Scrape Imperva (Incapsula)-Protected Websites
How to scrape Imperva (Incapsula)-protected websites without counting block pages as data: recognise Imperva from its cookies and headers, tell apart its four response shapes (terminal block, Pardon Our Interruption interstitial, thin page, served page) when most of them return HTTP 200, see why status, cookie and size checks fail, validate on the field you need, pace requests, and choose between an official API, permission or a managed browser API like GcrawlAI. With our own local lab results and pricing.
Bright Data Alternatives: 7 Cheaper Web Scraping APIs in 2026
Bright Data's Web Unlocker costs $1.50 per 1,000 requests. Here are seven cheaper web scraping APIs, from GcrawlAI to ScraperAPI, ScrapingBee, Oxylabs, Decodo, Zyte and Firecrawl, priced on the same workload once JavaScript and premium proxies are switched on, plus a safe way to migrate.
How to Scrape Kasada-Protected Websites With Python
How to scrape Kasada-protected websites with Python without fooling yourself: recognise the challenge (429 or 403 with x-kpsdk-* headers, an ips.js script on a UUID path, window.KPSDK), understand the detection layers, see why requests and httpx never get the page, catch silent 200 blocks by checking content instead of status codes, pace sessions, and choose between an official API, permission, or a managed browser API like GcrawlAI. With our own local lab results and third-party benchmark numbers.
Hidden API Scraping: Find the JSON Behind Any Website
Hidden API scraping, step by step: confirm the data isn't in the HTML, find the JSON request in DevTools or automatically with Playwright, replay it in Python, trim it to the headers that matter, refresh short-lived tokens, follow page, offset and cursor pagination, read embedded JSON like __NEXT_DATA__ and JSON-LD, and replay GraphQL. With our own lab results and what to do when the API is signed or blocked.