Gramosoft Insights
Scraping Insights For Modern AI Data
Discover strategies for structured data, crawling, scraping, LLMs, and RAG to build smarter and more efficient data workflows.
Latest Articles
10 Best Headless Browsers for Scraping in 2026: Playwright, Camoufox, Cloud Browsers and More
The 10 best headless browsers for web scraping in 2026: GcrawlAI, Playwright, Puppeteer, Selenium with SeleniumBase, Camoufox, nodriver, Patchright, CloakBrowser, Browserbase and Browserless, how sites detect headless browsers, and what 10,000 and 100,000 rendered pages a month cost on each, with prices checked on vendor pages.
9 Best Firecrawl Alternatives in 2026: Scraping APIs, Open Source and Agent Tools
The 9 best Firecrawl alternatives in 2026, with prices checked on each vendor's own pages: GcrawlAI, Crawl4AI, ScrapeGraphAI, Spider, Tavily, Bright Data, ScrapingBee, Apify and Jina Reader, what 10,000 pages a month costs on each, and a helper that moves Firecrawl-style code to GcrawlAI without changing your parsing.
9 Best Apify Alternatives in 2026: Scraping Without Compute Units
The 9 best Apify alternatives in 2026, with prices checked on each vendor's own pages: GcrawlAI, Firecrawl, Bright Data, Zyte, ScraperAPI, ZenRows, Octoparse, Browse AI and Scrapy, how Apify's compute units, proxy and Actor fees add up, and what 10,000 and 100,000 rendered pages a month cost on each.
How to Scrape Akamai-Protected Websites With Python
How to scrape Akamai-protected websites with Python: recognise Bot Manager (_abck, bm_sz and ak_bmsc cookies, the sensor script, Server: AkamaiGHost, Access Denied with a Reference # number), read its responses (hard block, 200 Pardon Our Interruption interstitial, 429), and keep sessions stable. Our local lab fetched 100 pages four ways: requests got 0 real of 20, a browser rotating its IP per request 5 of 20, a sticky IP with no delay 11 of 30, and a sticky IP at one page a second 30 of 30. Plus GcrawlAI (residential proxy, browser and stealth on every request), the Scrapeway Akamai benchmark, cost and responsible use.
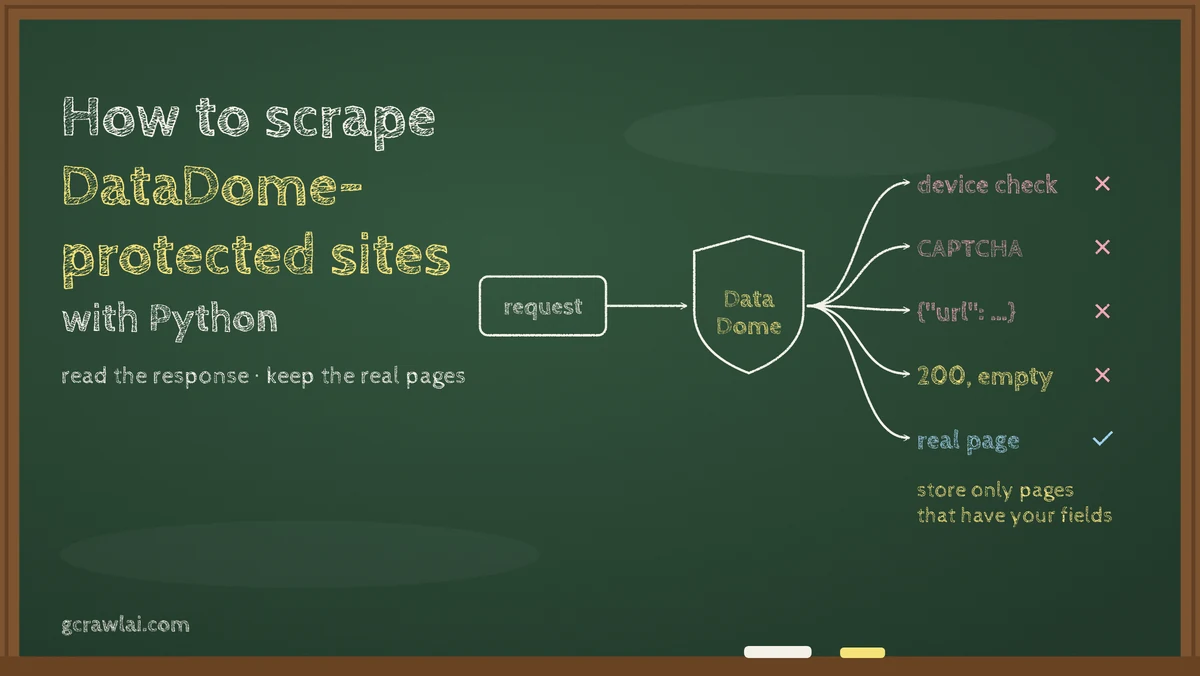
How to Scrape DataDome-Protected Websites With Python
How to scrape DataDome-protected websites with Python: recognise DataDome (x-datadome: protected, the datadome cookie, js.datadome.co/tags.js, captcha-delivery.com), tell its five responses apart (Device Check, CAPTCHA, 403 JSON challenge, empty 200 shell, allowed page), and store pages, not challenges. Our local lab scored four checks on 90 responses: only naming the response and checking expected fields got all 41 real pages and none of 49 challenges. Plus GcrawlAI (proxy, browser and stealth on every request), pace, cost and responsible use.
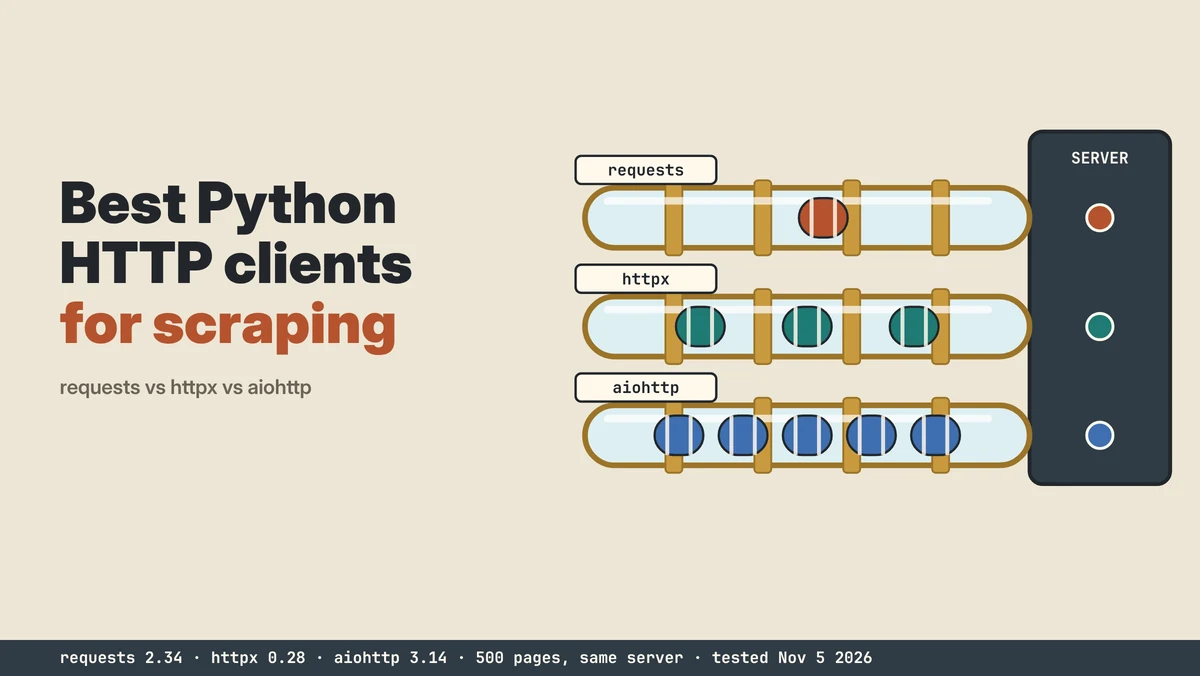
Best Python HTTP Clients for Scraping: requests vs httpx vs aiohttp
requests vs httpx vs aiohttp for Python web scraping: sync vs async, HTTP/2, default timeouts (none, 5 s, 300 s) and redirects (httpx doesn't follow them), install size and import time, our benchmark of 500 pages through nine client set-ups (aiohttp shared session 0.55 s, requests with 50 threads 0.59 s, httpx shared AsyncClient 1.00 s, httpx client per request 19.7 s), the four settings every scraper needs, cost, and why GcrawlAI never uses a plain HTTP client: every request goes through a proxy, a real browser and stealth mode.