
Gramosoft Insights
Scraping Insights For Modern AI Data
Discover strategies for structured data, crawling, scraping, LLMs, and RAG to build smarter and more efficient data workflows.
Browse by topic
Featured Post
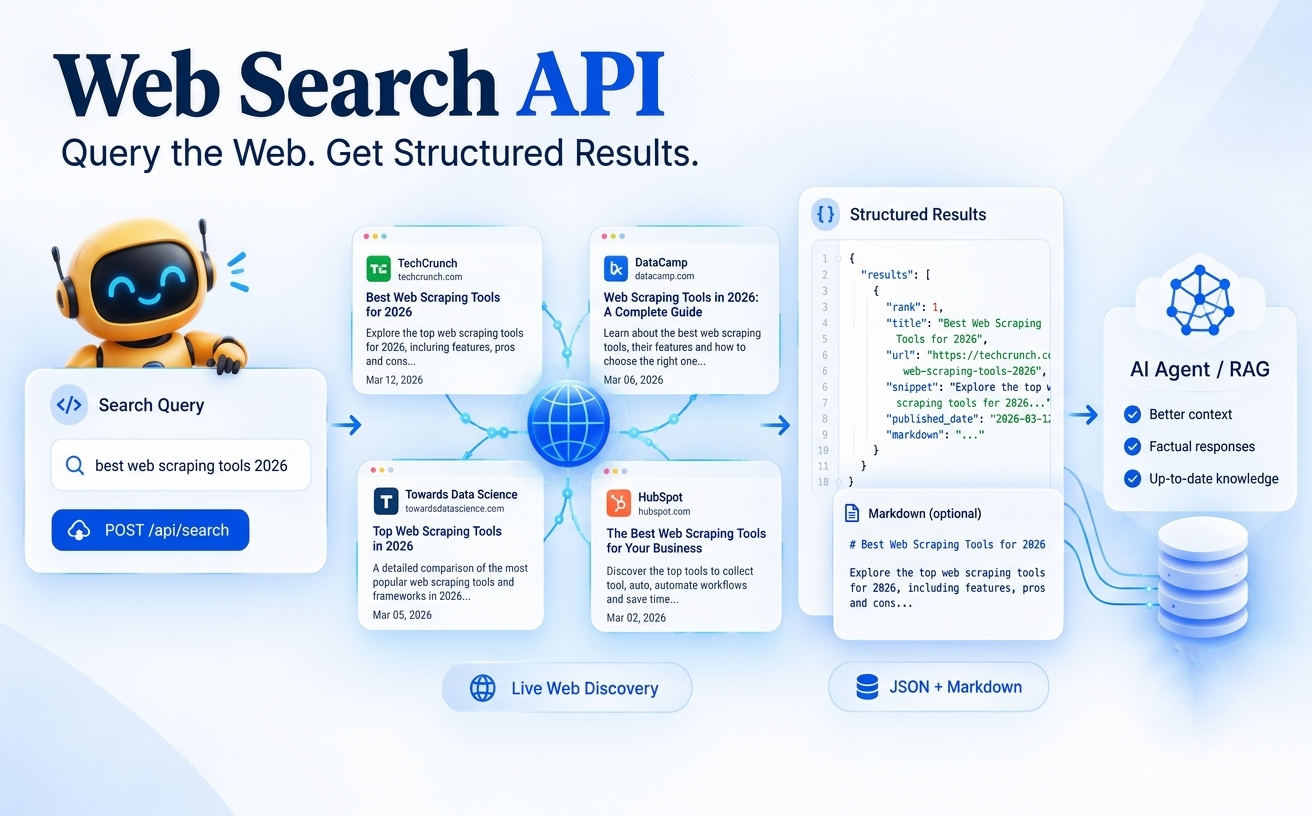
Web Search API: Query the Web and Get Structured Results
Not every data project starts with a known URL. Query the live web programmatically and receive clean, structured JSON results with optional pre-scraped Markdown — powered by one flat-rate API.
Read full articleLatest Articles
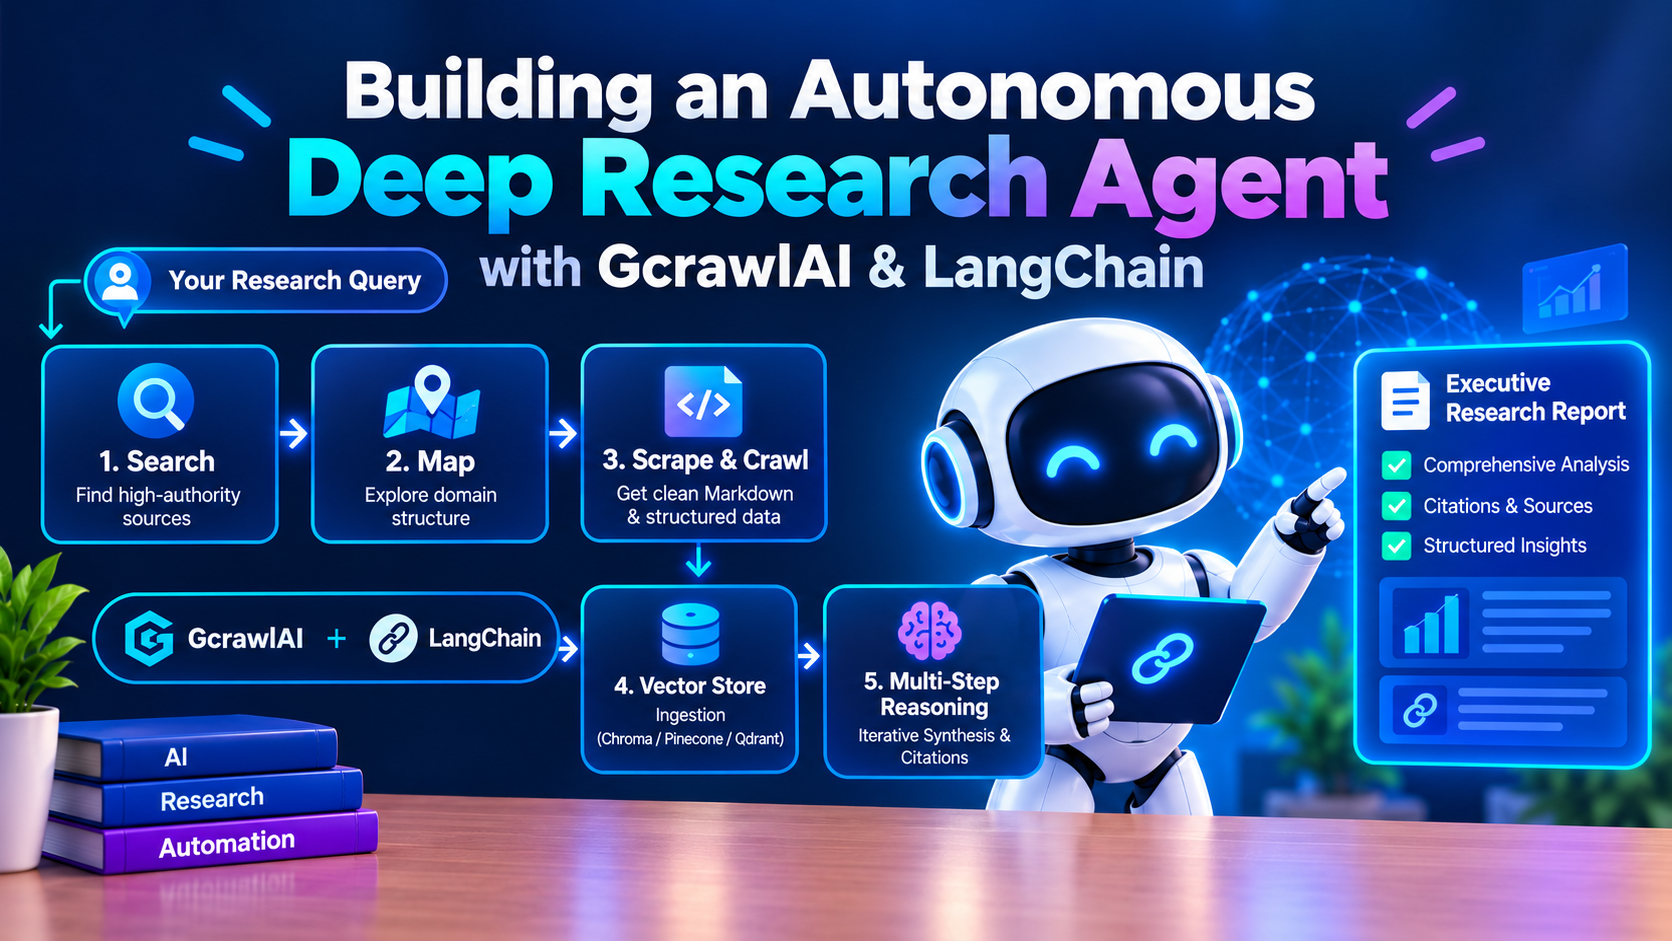
Building an Autonomous Deep Research Agent with GcrawlAI & LangChain
The complete 2026 architectural blueprint: how to turn the live web into token-efficient knowledge bases for multi-step AI research without credit multiplier traps.
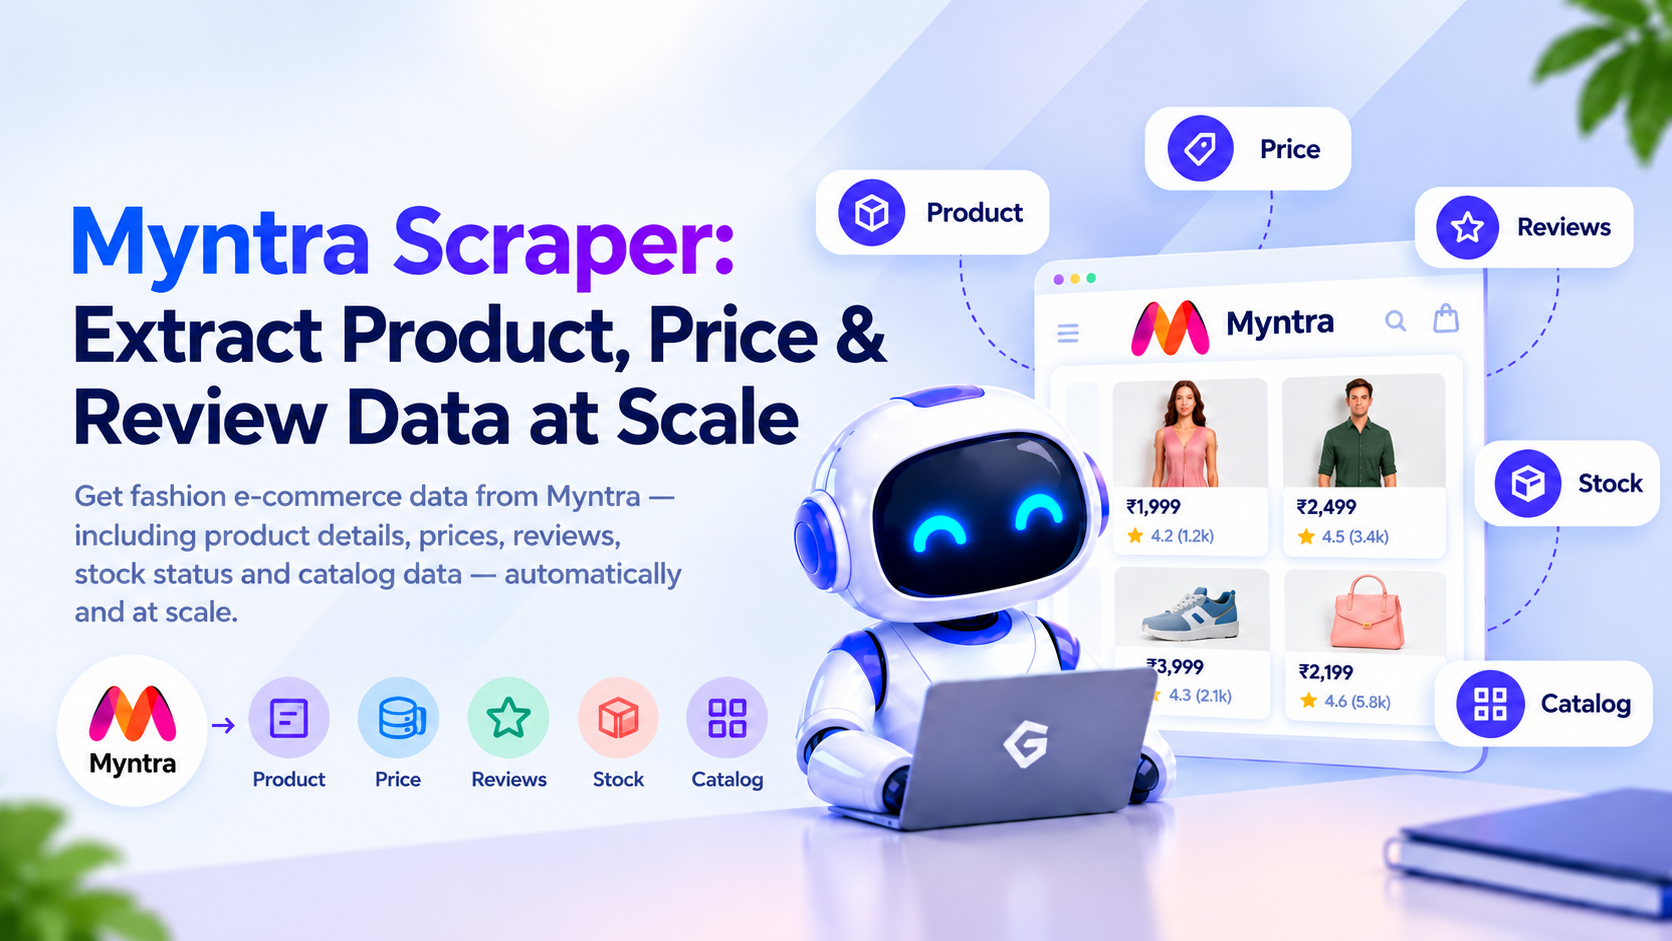
Myntra Scraper: Extract Product, Price & Review Data at Scale
Learn how a Myntra scraper can extract product, pricing, reviews, variants, images, stock, and catalog data at scale. Explore practical use cases, technical challenges, monitoring strategies, legal considerations, and how GcrawlAI can turn web content into structured, AI-ready data.
What If Your AI Could Read 10,000 Websites?
What if your AI could read 10,000 websites? Large-scale web crawling helps AI systems collect, clean, structure, and connect live web data to RAG systems, AI agents, competitive intelligence, research, price monitoring, and automated data pipelines.
7 Cheapest Reliable Web Scraping APIs for High Volume in 2026
High-volume web scraping can become expensive when hidden costs such as JavaScript rendering multipliers, failed requests, proxy charges, and raw HTML processing add up. This guide compares 7 reliable web scraping APIs in 2026, focusing on real cost per request, rendering costs, failure handling, and AI-ready output. It also explains how 1:1 request-based billing can simplify high-volume scraping and reduce unexpected costs.
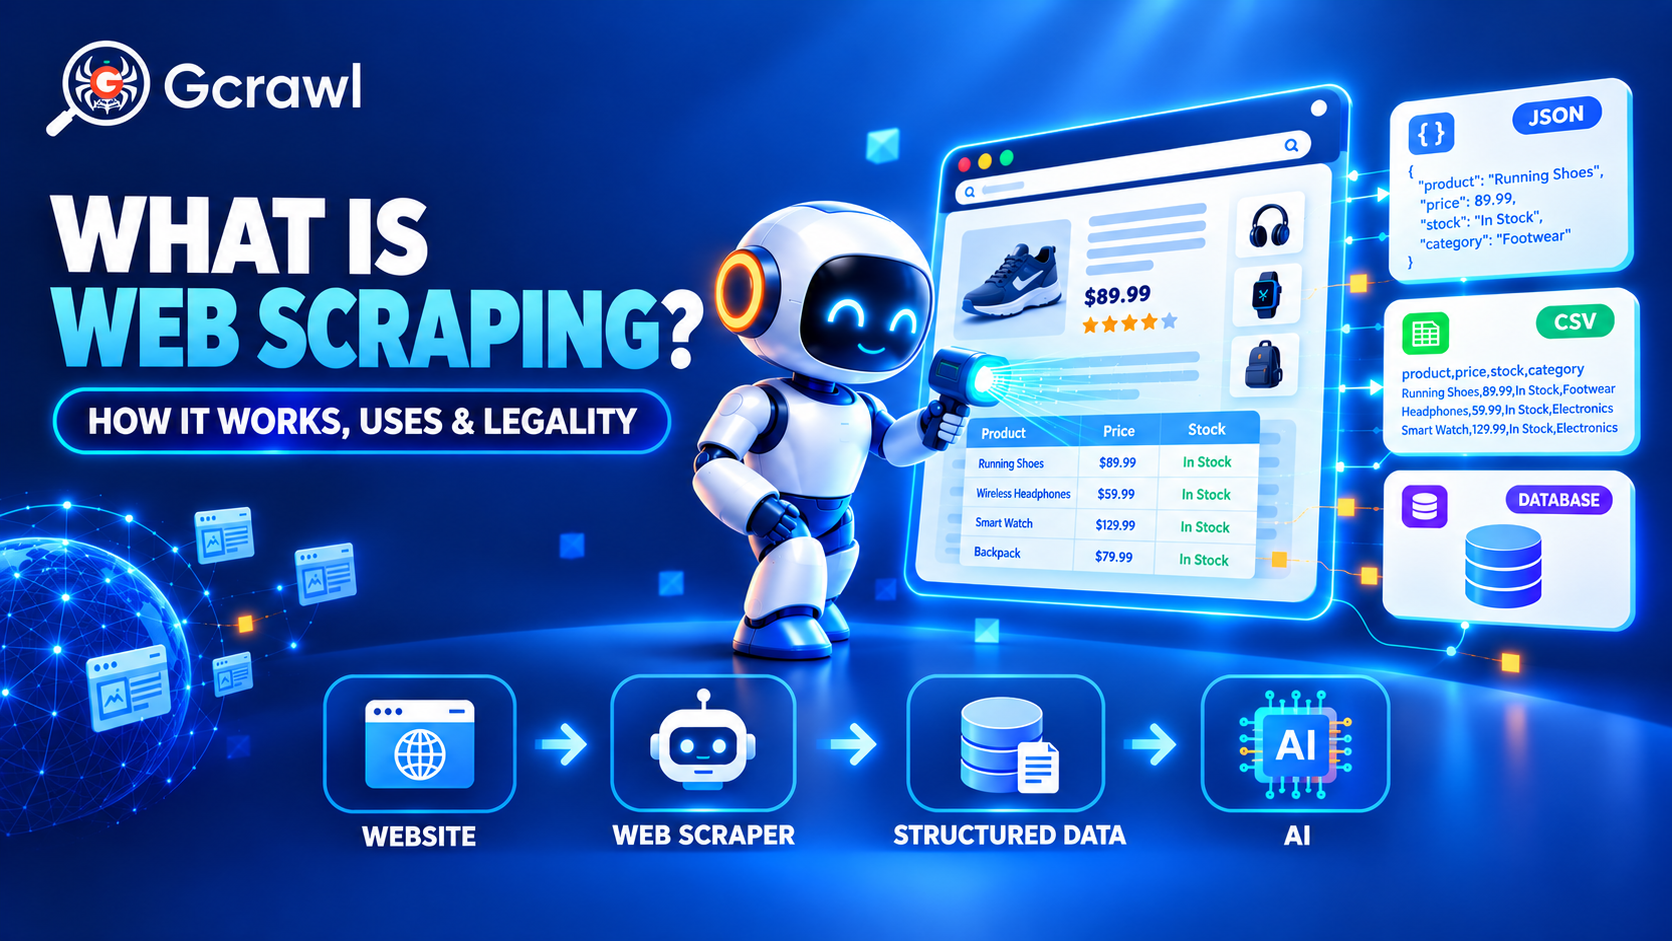
What Is Web Scraping? How It Works, Uses & Legality
Learn what web scraping is, how it works, the difference between scraping and crawling, common scraping challenges, static vs. dynamic websites, AI and RAG use cases, and the legal and ethical considerations of collecting public web data.