
Gramosoft Insights
Scraping Insights For Modern AI Data
Discover strategies for structured data, crawling, scraping, LLMs, and RAG to build smarter and more efficient data workflows.
Featured Post
Best RAG Frameworks in 2026
The best RAG frameworks in 2026 compared: GsearchAI as a ready-made enterprise platform combining graph RAG and vector RAG, then LangChain with LangGraph, LlamaIndex, Haystack, DSPy, RAGFlow, LightRAG, Microsoft GraphRAG, txtai, Cognee, Mastra and Microsoft Agent Framework, with licences, maintenance status, install footprint and import times, evaluation options, our own loader lab (every default web loader lost the same six JavaScript-built pages; rendered Markdown took retrieval from 6 to 11 or 12 of 12), cost, and where GcrawlAI fits as the ingestion step.
Read full articleLatest Articles
Web Scraping With LlamaIndex: Load Any Website Into Your Index
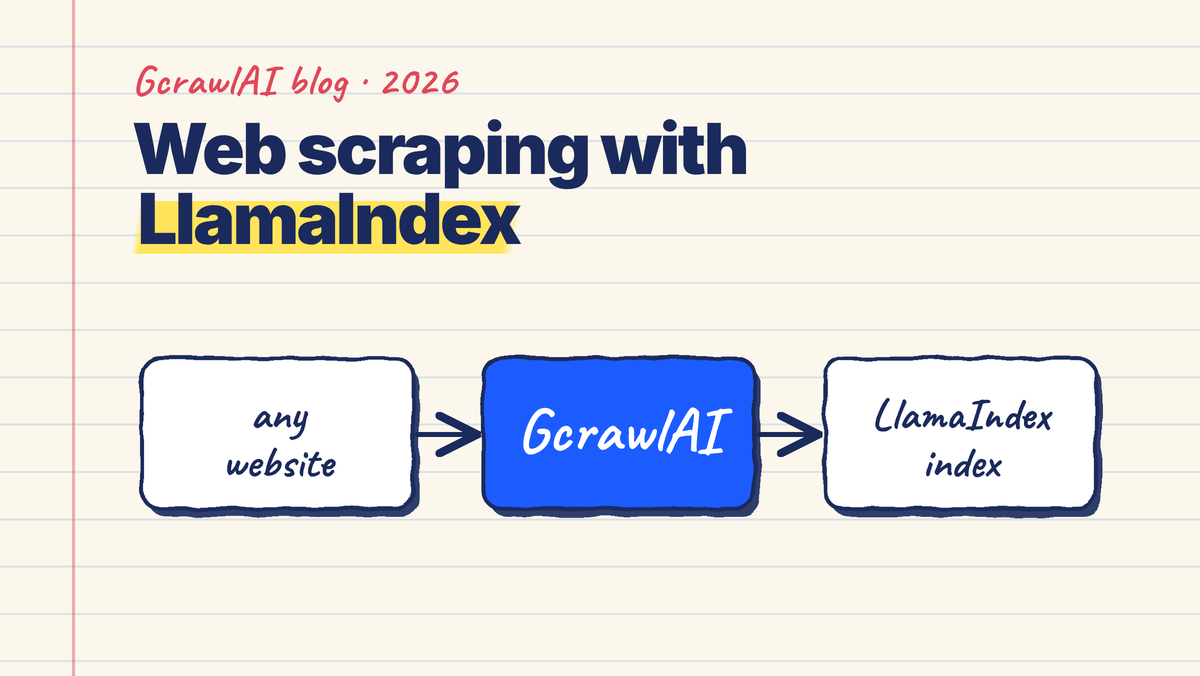
How to load any website into a LlamaIndex index in 2026: a short GcrawlAI reader that returns rendered Markdown for URLs, a whole site or one section, an architecture diagram of the full pipeline, an IngestionPipeline that re-embeds only changed pages and never deletes after a partial crawl, and a FunctionAgent with live web search.
How to Crawl an Entire Website: Sitemap and Link Discovery
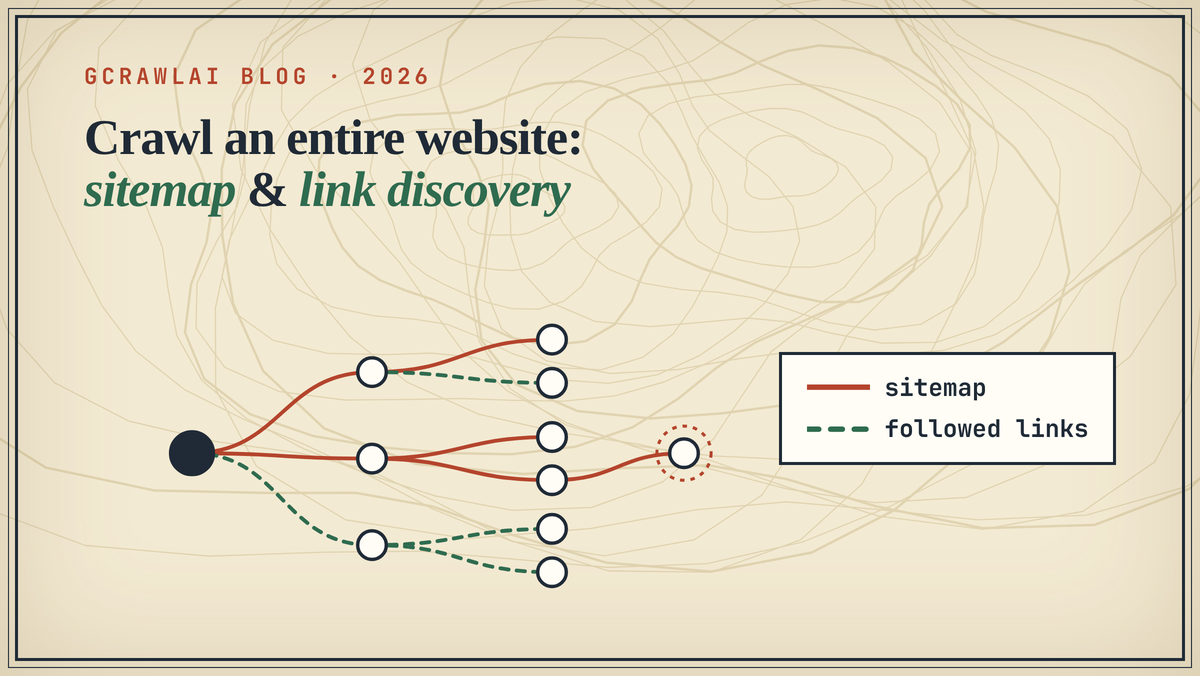
How to find every page on a website: read sitemaps from robots.txt, follow sitemap indexes and gzipped files, then run a breadth-first link crawl with URL normalisation, depth and per-path caps and JavaScript rendering. On a 73-page test site, only the two methods combined found every page. Includes Python code and the GcrawlAI map and crawl version.
Cloudflare Error 1015 "You Are Being Rate Limited": How to Fix It
Error 1015 "You are being rate limited" means a website's Cloudflare rate limiting rule paused you. Learn how long it lasts on each Cloudflare plan, how to fix it as a visitor, how scrapers should pace and back off (with Python code), and how site owners stop it blocking real visitors.
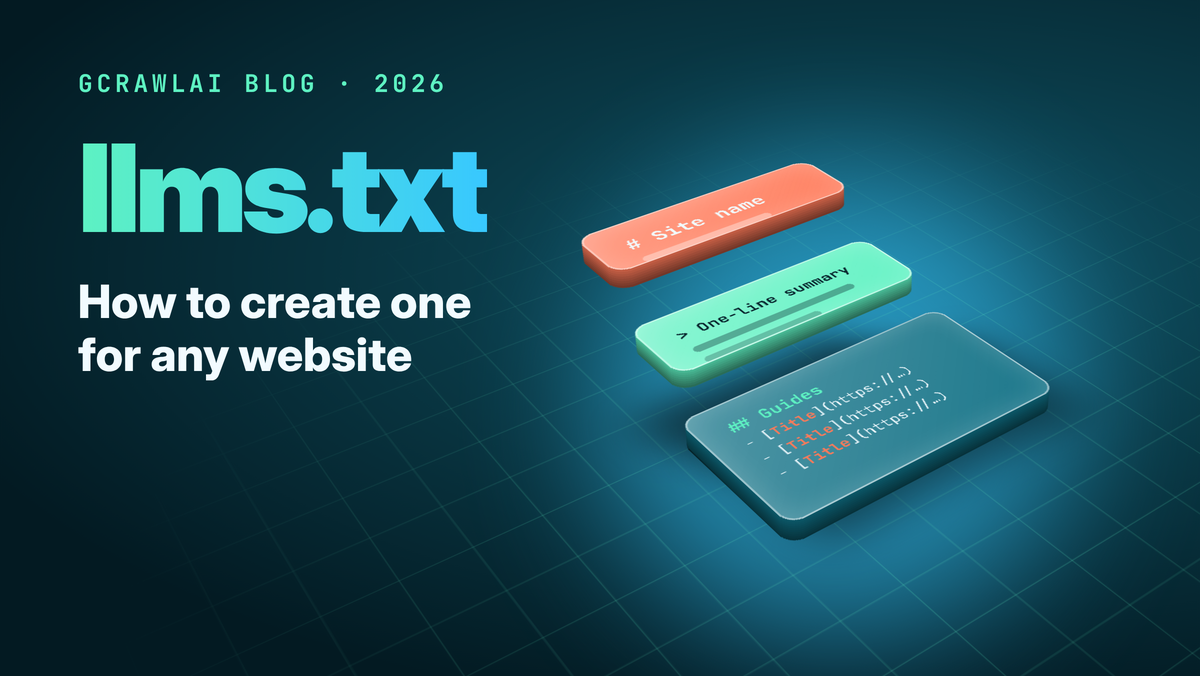
How to Create an llms.txt File for Any Website
llms.txt is a short Markdown index that tells AI agents which pages on your site matter. Learn the format, write one by hand, generate one from your sitemap or a GcrawlAI crawl, publish it on any platform and check it before it goes live.
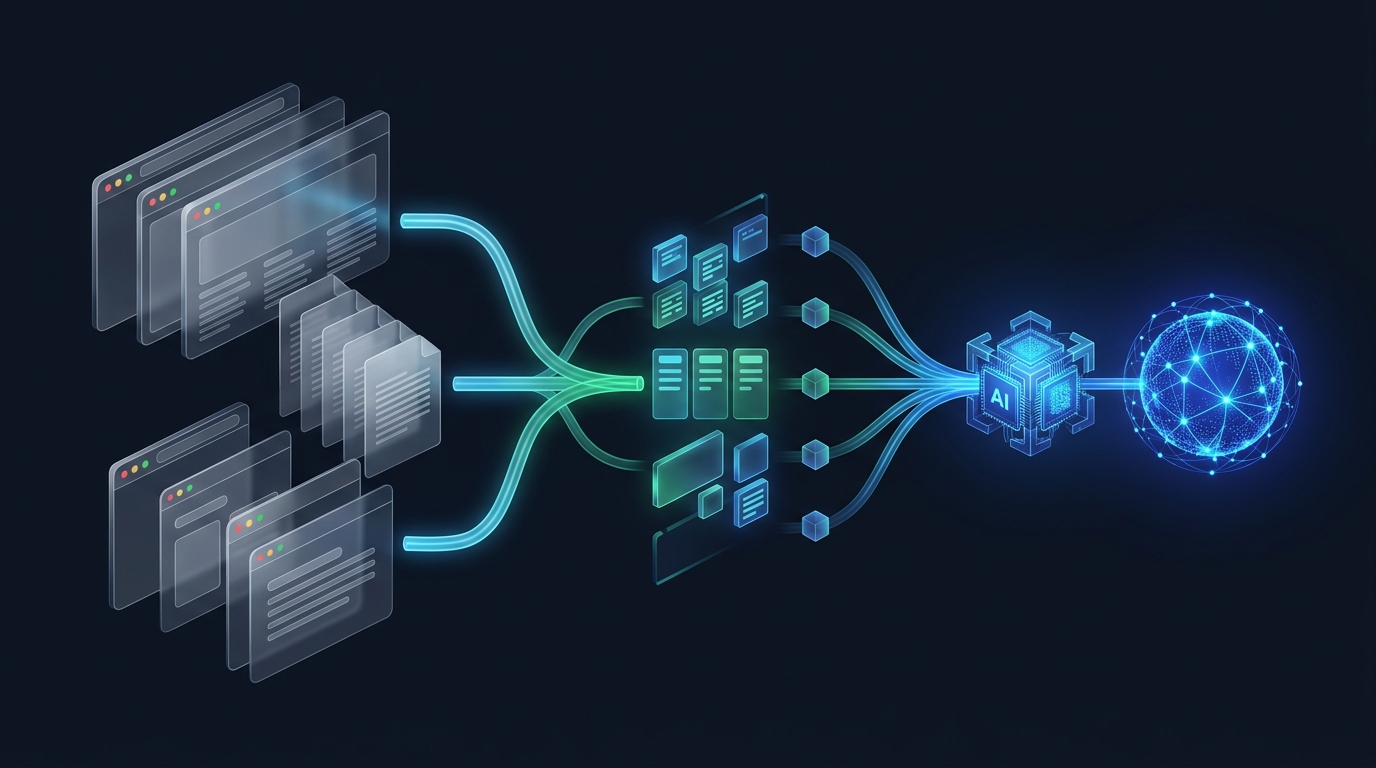
Website Data for LLM: How to Extract Clean, Token-Efficient Web Data for AI & RAG (2026 Guide)
Learn how to extract clean website data for LLMs in 2026. Discover why raw HTML bloats context windows, how semantic Markdown cuts token usage by 82%, and how GcrawlAI automates JS rendering, anti-bot stealth, and MCP agent grounding.
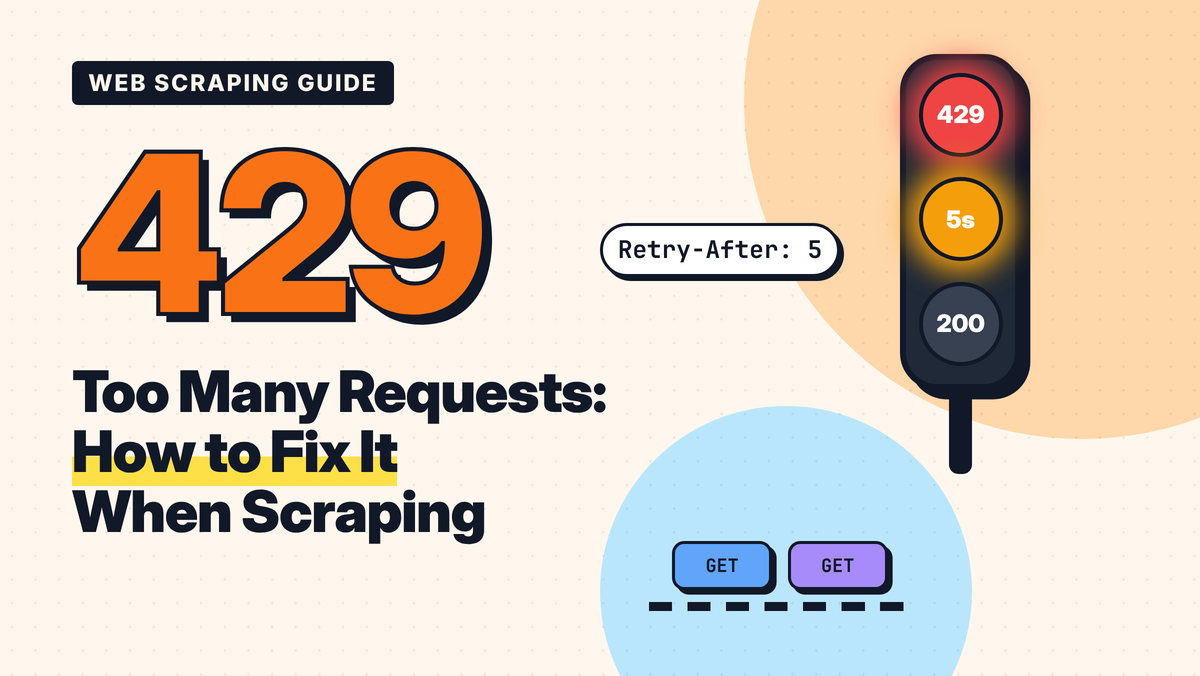
429 Too Many Requests: How to Fix It When Web Scraping
A 429 means you hit a rate limit, and the server often tells you exactly how long to wait. Here's how to read it, then eight fixes from Retry-After and backoff to pacing, concurrency limits, proxies and Scrapy settings, each tested against a rate-limited site.