Why Companies Are Switching from Firecrawl to GcrawlAI: The Hidden Cost of 5x Credit Multipliers
If you have ever built an AI agent, RAG pipeline, or web data extraction engine using legacy scraping APIs, chances are you have experienced credit sticker shock.
You sign up for a plan advertising 100,000 “credits” per month, expecting to scrape 100,000 pages. But by day seven of production, your quota is drained. Why? Because the modern web is built on dynamic JavaScript (React, Next.js, Vue) protected by anti-bot firewalls (Cloudflare Turnstile, DataDome). On platforms like Firecrawl and ScrapingBee, enabling JavaScript rendering and residential proxies instantly triggers 5x to 15x credit multipliers.
Suddenly, each single URL scrape doesn’t cost 1 credit—it burns 5 to 15 credits. A planned 100,000-page crawl actually yields only 6,500 to 20,000 usable pages before your bill balloons into hundreds or thousands of dollars.
The Anatomy of the Credit Multiplier Trap
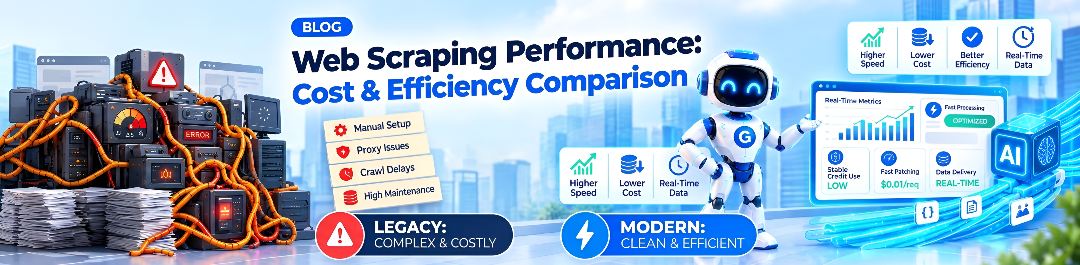
To understand why engineering teams are making the switch, look at how legacy scraping APIs calculate billable usage versus GcrawlAI:
❌ The Legacy "Credit System" (Firecrawl / ScrapingBee)
- Basic HTML Scrape: 1 Credit
- JavaScript Execution: 5x Multiplier (Burns 5 credits per page)
- Residential Proxy Rotation: 10x to 15x Multiplier (Burns 10–15 credits)
- Failed Scrapes: Often deducted regardless of target timeouts
- Result: Unpredictable invoices and unexpected mid-month service halts
✅ Transparent 1:1 Request Billing (GcrawlAI)
- Basic HTML Scrape: 1 Request
- JavaScript Rendering: Included (Still 1 Request)
- Residential Proxy Escalation: Included (Still 1 Request)
- Anti-Bot Evasion (Cloudflare Turnstile): Included (Still 1 Request)
- Failed Scrapes Guarantee: 5xx server errors billed at strictly 0 requests
Feature-by-Feature Comparison: Firecrawl vs. GcrawlAI
Here is how GcrawlAI directly compares against Firecrawl across core technical capabilities, developer tooling, and pricing economics:
| Capability / Feature | Firecrawl | GcrawlAI |
|---|---|---|
| Billing Unit | Credits (Opaque multipliers) | Flat 1 Request = 1 Request |
| JavaScript Rendering Surcharge | 5x credit deduction | Included at 0 extra cost |
| Residential Proxy Surcharge | 10x to 15x deduction | Included standard |
| Free Monthly Tier | 500 credits (~100 JS scrapes) | 200 Requests / Mo Forever |
| Website to Offline ZIP Cloner | Not available | Native Tool (/offline-bundle-zip/) |
| Live Search API with Markdown | Basic SERP | Real-Time SERP + Clean Markdown (/search/) |
| Model Context Protocol (MCP) | Community wrapper | First-class native MCP server |
| Data Security & Compliance | SOC 2 | ISO 9001:2015 & ISO 27001:2022 (RAM-only ephemeral processing) |
The Real-World Math: 100,000 Scrapes per Month
Let’s calculate the actual invoice cost for an AI product or data team scraping 100,000 dynamic URLs (e.g., e-commerce products, financial reports, or competitor news) per month:
- On Firecrawl:
100,000 scrapes × 5 credits (for JS rendering) = 500,000 credits. At standard tiered pricing, you are forced into an Enterprise or Growth plan costing between $400 to $800+ USD per month.
- On GcrawlAI:
100,000 scrapes = 100,000 requests. Under GcrawlAI’s Growth plan, this costs exactly ₹7,900 INR (~$95 USD) per month.
The result: Teams save over 75% to 85% on annual scraping infrastructure costs while gaining faster response times and predictable budgeting.
Migrating from Firecrawl in 2 Minutes
Because GcrawlAI follows standard REST conventions and returns clean Markdown and structured metadata, migrating existing Python or Node.js scripts is a drop-in replacement:
# Before: Burning 5x credits per scrape on legacy providers
# After: Flat 1 Request on GcrawlAI

import requests

def scrape_page(url: str):
    endpoint = "https://api.gcrawlai.com/v1/scrape"
    headers = {
        "Authorization": "Bearer YOUR_GCRAWLAI_API_KEY",
        "Content-Type": "application/json"
    }
    payload = {
        "url": url,
        "formats": ["markdown"],
        "onlyMainContent": True,
        "waitFor": 1500  # Full JavaScript rendering included at 1 request
    }

    response = requests.post(endpoint, json=payload, headers=headers)
    return response.json()["data"]["markdown"]

# Clean, LLM-ready Markdown delivered in <400ms
markdown = scrape_page("https://example.com/dynamic-spa")
print(markdown[:300])
Why GcrawlAI's Markdown Saves Thousands in LLM Token Costs
Cost savings don’t stop at the scraping layer. When feeding scraped data into LLMs (GPT-4o, Claude 3.5 Sonnet, Gemini 1.5 Pro) for RAG or agent reasoning, raw HTML consumes massive token budgets on headers, navigation bars, SVG icons, and tracking scripts.
By enabling onlyMainContent: true, GcrawlAI’s proprietary heuristic parser isolates the core article, document, or product body and discards page clutter. This reduces token ingestion by up to 80%, speeding up LLM inference and preventing context-window overflows.
Conclusion: Predictable Infrastructure for the AI Era
Modern AI applications cannot scale on volatile, opaque credit systems. As data extraction becomes a primary bottleneck for reasoning agents and real-time knowledge retrieval, transparency and speed win.
Whether you need to scrape single dynamic URLs, crawl entire domains, map sitemaps, or query live web search results, GcrawlAI provides the enterprise-grade foundation your engineering team needs.
- Test live URL extraction in our interactive GcrawlAI Playground.
- Read our comprehensive comparison breakdown: GcrawlAI vs. Firecrawl.
- Review our transparent, credit-free pricing tiers at gcrawlai.com/pricing.
Frequently asked questions
Is GcrawlAI a drop-in alternative to Firecrawl?
<p>Yes. GcrawlAI provides equivalent endpoints for single-page scraping (/scrape), full domain crawling (/crawl), and URL discovery (/map), while returning clean, LLM-ready Markdown and structured JSON. Migrating existing scripts requires only updating your API key and base endpoint URL.</p>
Does GcrawlAI charge extra credits for JavaScript rendering or residential proxies?
<p>No. GcrawlAI operates strictly on transparent 1 Request = 1 Request billing. Headless Chromium execution, anti-bot evasion (Cloudflare Turnstile, DataDome), and rotating residential proxies are completely included at 1 request with zero multipliers.</p>
What happens if a scrape request fails due to a server error or timeout?
<p>Unlike legacy providers that bill credits on failed requests, GcrawlAI guarantees that 5xx server errors and unresolvable timeouts cost strictly 0 requests. You only pay for successfully extracted web content.</p>
How many free requests do I get on GcrawlAI?
<p>GcrawlAI provides 200 free requests every month forever. Every request includes full JavaScript rendering, Markdown extraction, and residential proxies with no credit deduction surprises.</p>