Gramosoft & GcrawlAI at Open Source India 2026: Showcasing Open-Source Web Intelligence at Booth SA-3
Open Source India 2026 has officially kicked off at the prestigious NIMHANS Convention Centre in Bangalore on October 7–8, 2026, and the Gramosoft team is thrilled to be on the ground connecting with thousands of software engineers, AI researchers, enterprise innovators, and open-source creators.
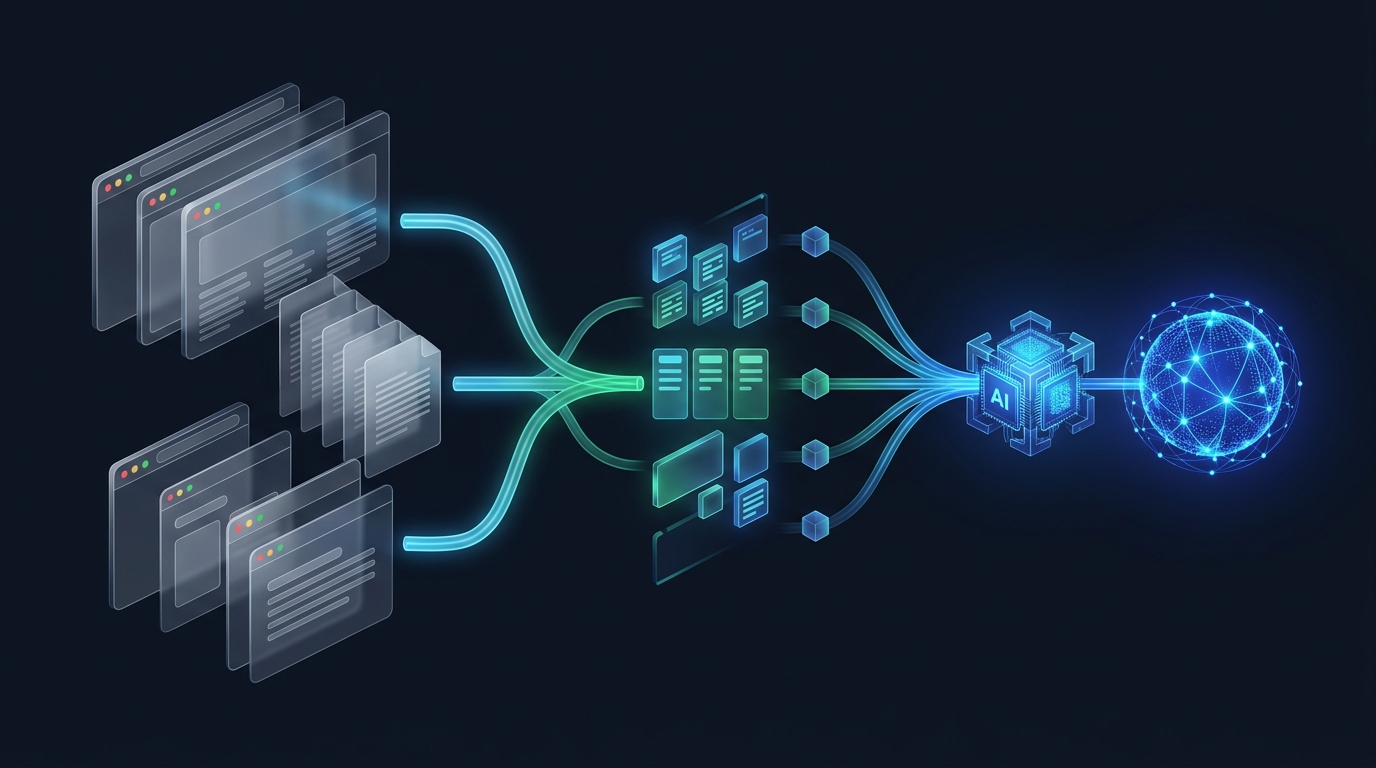
At our dedicated showcase at Booth SA-3, we are unveiling GcrawlAI — our high-performance, developer-first AI web crawling and data extraction platform engineered to solve one of the biggest challenges in production AI: transforming dynamic, messy web content into clean, structured, AI-ready data.
The Next Frontier: Turning the Web into AI-Ready Data
Modern AI agents, LLM applications, and Retrieval-Augmented Generation (RAG) pipelines require fresh, factual, and accurate knowledge. However, engineering teams face significant roadblocks when attempting to feed live web data into their models:
Traditional Scraping Roadblocks
- Fragile headless browser pools requiring constant DevOps maintenance
- Aggressive bot mitigation (Cloudflare, PerimeterX, CAPTCHAs) blocking crawlers
- Noisy, script-heavy HTML payloads burning up to 80% redundant tokens
- Predatory 5x–15x credit multipliers eating startup and enterprise budgets
- Slow multi-second turnaround times halting interactive agent responses
The GcrawlAI Solution
- Fully managed Chromium browser clusters with automated residential IP rotation
- Smart stealth bypass solving dynamic JavaScript and anti-bot obstacles natively
- Pristine, token-optimized Markdown output ready for LLMs and vector embeddings
- Predictable 1:1 request billing with zero hidden credit multipliers
- Blazing-fast sub-400ms turnaround for live web search and RAG pipelines
What Gramosoft is Showcasing at Booth SA-3
Throughout the two days of Open Source India 2026, our booth has been packed with developers exploring live interactive demos across four core capability pillars:
Web Crawling & Scrape
Deep autonomous recursive site mapping, domain crawling, and single-page scraping with full-page screenshot support.
URL to Markdown & JSON
Instant parsing of complex web pages into structured, noise-free Markdown optimized for prompt contexts and token savings.
Live Web Search API
Sub-400ms programmatic search queries returning structured results with live full-page Markdown content in one request.
Enterprise & Self-Hosted
Open-source architecture with ISO 27001-certified enterprise hosting and on-premises deployment options.
Event Highlights: Days 1 & 2 at NIMHANS Convention Centre
Here is what attendees are experiencing first-hand at Booth SA-3 during Open Source India 2026:
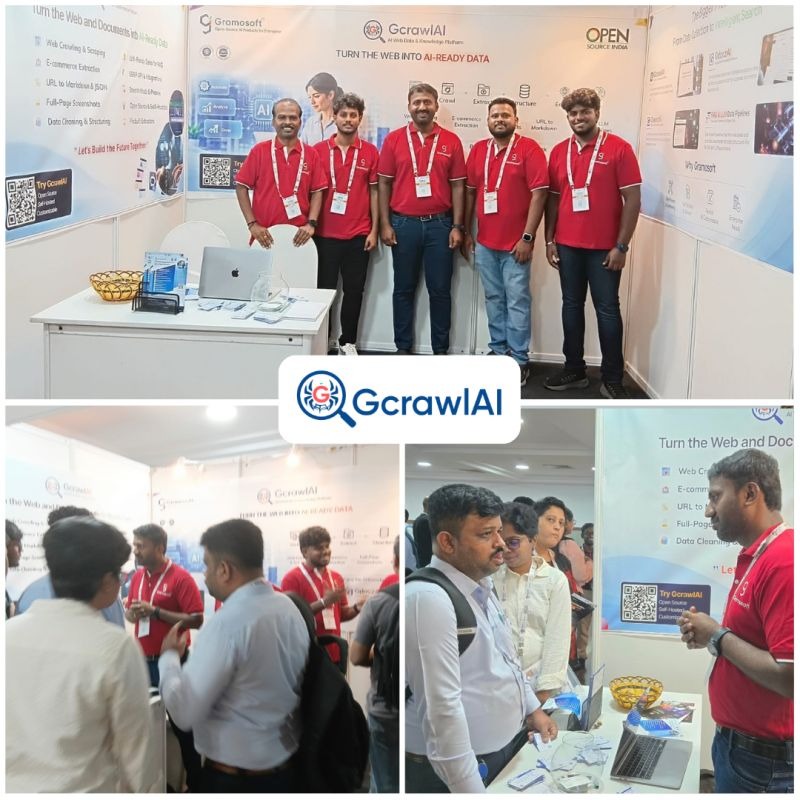
Booth SA-3 Showcase Opening
The Gramosoft leadership and engineering team opened Booth SA-3 in the main exhibition hall, welcoming attendees with live demos and GcrawlAI starter credits.
Interactive Live Scraping Demos
Visitors tested GcrawlAI against challenging modern websites — witnessing how dynamic single-page applications convert to clean Markdown in under 400 milliseconds.
Architectural Q&A on Corrective RAG
Engineering discussions on integrating GcrawlAI with LangChain, LangGraph, and LlamaIndex to eliminate LLM hallucinations using real-time web search verification.
Community Partnerships & Ecosystem
Connecting with enterprise CTOs, startup founders, and open-source contributors to expand the GcrawlAI open-source data tooling ecosystem across India.
Quickstart: How Developers are Using GcrawlAI
At OSI 2026, developers were amazed by how straightforward it is to extract clean Markdown using standard Python:
import requests

GCRAWLAI_API_KEY = "your-gcrawlai-api-key"

# Scrape any dynamic JavaScript URL directly into clean Markdown
response = requests.post(
    "https://api.gcrawlai.com/v1/scrape",
    headers={"Authorization": f"Bearer {GCRAWLAI_API_KEY}"},
    json={
        "url": "https://example.com/dynamic-page",
        "renderJs": True,
        "format": "markdown"
    },
    timeout=10
)

data = response.json()
print("Clean Markdown for AI Agent Context:")
print(data.get("markdown")[:500])
Platform Comparison: GcrawlAI vs. Other Approaches
| Feature | Traditional DIY Scrapers | Legacy Scraping APIs | GcrawlAI Platform |
|---|---|---|---|
| Architecture | Custom Puppeteer / Selenium | Closed SaaS Blackbox | Open-Source & Cloud API |
| Pricing Model | Heavy Server / DevOps Cost | 5x–15x Credit Multipliers | Flat 1:1 Request Billing |
| Output Format | Raw, messy HTML | Basic HTML / JSON | AI-Ready Clean Markdown & JSON |
| Latency (p90) | 3.5s – 6.0s | 2.5s – 4.0s | ~380ms Sub-Second Dispatch |
| Deployment | Self-managed only | Cloud-only | Cloud, Self-Hosted, or On-Prem |
Visit Gramosoft at Booth SA-3 Today!
If you are attending Open Source India 2026 today at NIMHANS Convention Centre, Bangalore, don't miss the chance to meet our core engineering team in person.
Whether you're building autonomous AI agents, fine-tuning large language models, running high-volume e-commerce intelligence, or looking for self-hosted enterprise crawling infrastructure — we'd love to explore how GcrawlAI can empower your workflow.
Event Quick Reference
- Event: Open Source India (OSI) 2026
- Venue: NIMHANS Convention Centre, Bangalore, Karnataka
- Booth: Booth SA-3 (Gramosoft & GcrawlAI)
- Dates: 7–8 October 2026
- Official Website: https://gcrawlai.com/
- Playground & Extractors: https://gcrawlai.com/extractors
Frequently asked questions
Where is the Gramosoft & GcrawlAI booth located at Open Source India 2026?
<p>The Gramosoft team is showcasing GcrawlAI at Booth SA-3 at the NIMHANS Convention Centre in Bangalore on 7–8 October 2026.</p>
What is GcrawlAI?
<p>GcrawlAI is an open-source AI web crawling and data extraction platform that converts complex, dynamic web pages into structured, token-optimized Markdown and JSON for LLMs, RAG pipelines, and AI agents.</p>
Can GcrawlAI be self-hosted on enterprise infrastructure?
<p>Yes! In addition to our managed cloud API, GcrawlAI offers self-hosted and on-premises deployment options backed by Gramosoft's ISO 27001-certified enterprise support.</p>
How does GcrawlAI pricing work?
<p>GcrawlAI features transparent flat 1:1 request billing (1 request = 1 scrape) with zero credit multipliers for JavaScript rendering or residential proxy rotation.</p>